Overview
Two Python scripts bring what Collibra knows about your warehouse into Validatar, and a third prepares Collibra for the results Validatar publishes:
collibra_custom_metadata.pyfills the Collibra section of the Validatar catalog on one warehouse data source: asset ids and links, descriptions, statuses, owners and stewards, tags, business terms, data categories, security classification, personal data flags, accepted data classes and any Collibra attribute you name, at data source, schema, table and, optionally, column level.collibra_lineage.pyloads Collibra's column lineage between the databases you list as Validatar lineage, at table or column level, so a failed test shows what sits downstream.collibra_setup.pycreates the Validatar Data Quality domain in Collibra and checks the attributes, relation types and dimensions Validatar's rules need. A Collibra admin runs it once. Collibra Setup for Validatar covers it in full.
They are part of the Collibra Integration. Publishing Validatar results to Collibra is done by the Collibra Data Source Template, not by these scripts.
Marketplace: Collibra Metadata and Lineage Scripts (a download; it is not imported)
What is in the download
| File | What it is |
|---|---|
collibra_custom_metadata.py |
The metadata script. Paste it into a Custom Metadata source on a warehouse data source |
collibra_lineage.py |
The lineage script. Paste it into a Lineage Ingestion source |
collibra_setup.py |
Prepares Collibra for Validatar's results. Run once, by a Collibra admin |
collibra_helpers.py |
Shared code for running the scripts from the command line. Inside Validatar the Collibra data source template provides the same code |
README.md, README.docx |
The full guide: every setting, every field filled, setup steps and troubleshooting |
requirements.txt, VERSION |
Python packages for command-line use, and the package version |
How the pieces fit
Every Collibra connection in Validatar uses the Collibra data source template with the same settings: the same Collibra URL and the same credentials. What differs from one warehouse to the next sits at the top of the script, in plain Python:
# ---- 1. WHICH COLLIBRA DATABASE ----
COLLIBRA_DATABASE_FULL_NAME = "Snowflake-Connection>SAMPLE_DW"
ONLY_SCHEMAS = []                # e.g. ["PUBLIC", "FINANCE"]; empty means all
A database registered in Collibra through Edge gives every asset under it a full name that starts with the Edge connection's name and the database: Snowflake-Connection>SAMPLE_DW>STAR_SCHEMA>FACT_SALES is a table, and a column adds >CUSTOMER_KEY(column). The scripts find your tables by that prefix. The Collibra data source's own catalog in Validatar lists every database with its full name, in schema Database.
Below section 1, section 2 switches each field on or off, and a block describes the dataframes the script returns, with an example row. The template's pre-execution script carries the shared code: the Collibra client, the Validatar client and name matching. The client uses the Python standard library only, so there is nothing to install, and it reads in bulk through Collibra's Knowledge Graph GraphQL API.
To connect another warehouse, copy the script into that data source's Custom Metadata source and change section 1. Each process has its own connection, so enter the same Collibra settings on each.
Before you start
- From the marketplace, import the Collibra Data Source Template and the Collibra Catalog Custom Fields. The fields must exist before the first run: Validatar ignores a script column that has no field with the same reference key.
- In Collibra: Collibra Platform 2024.02 or later, and an Integration OAuth application, or a user name and password for Basic sign-in. Its user needs read access to the physical data dictionary domains of your databases.
- In Validatar: Govern Edition for catalog custom fields; for lineage, the Data Lineage feature and the Global Lineage Metadata Admin role.
- Run technical metadata ingestion on your warehouse data sources first. The scripts only write to schemas, tables and columns that Validatar has cataloged.
What the metadata script brings back
| Level | Fields |
|---|---|
| Data source | Collibra Database Full Name, Database Name, Edge Connection, Database Domain, Database Link, Data Source Synced |
| Schema | Collibra Schema Full Name, Link, Description, Status, Tags, Domain, Synced |
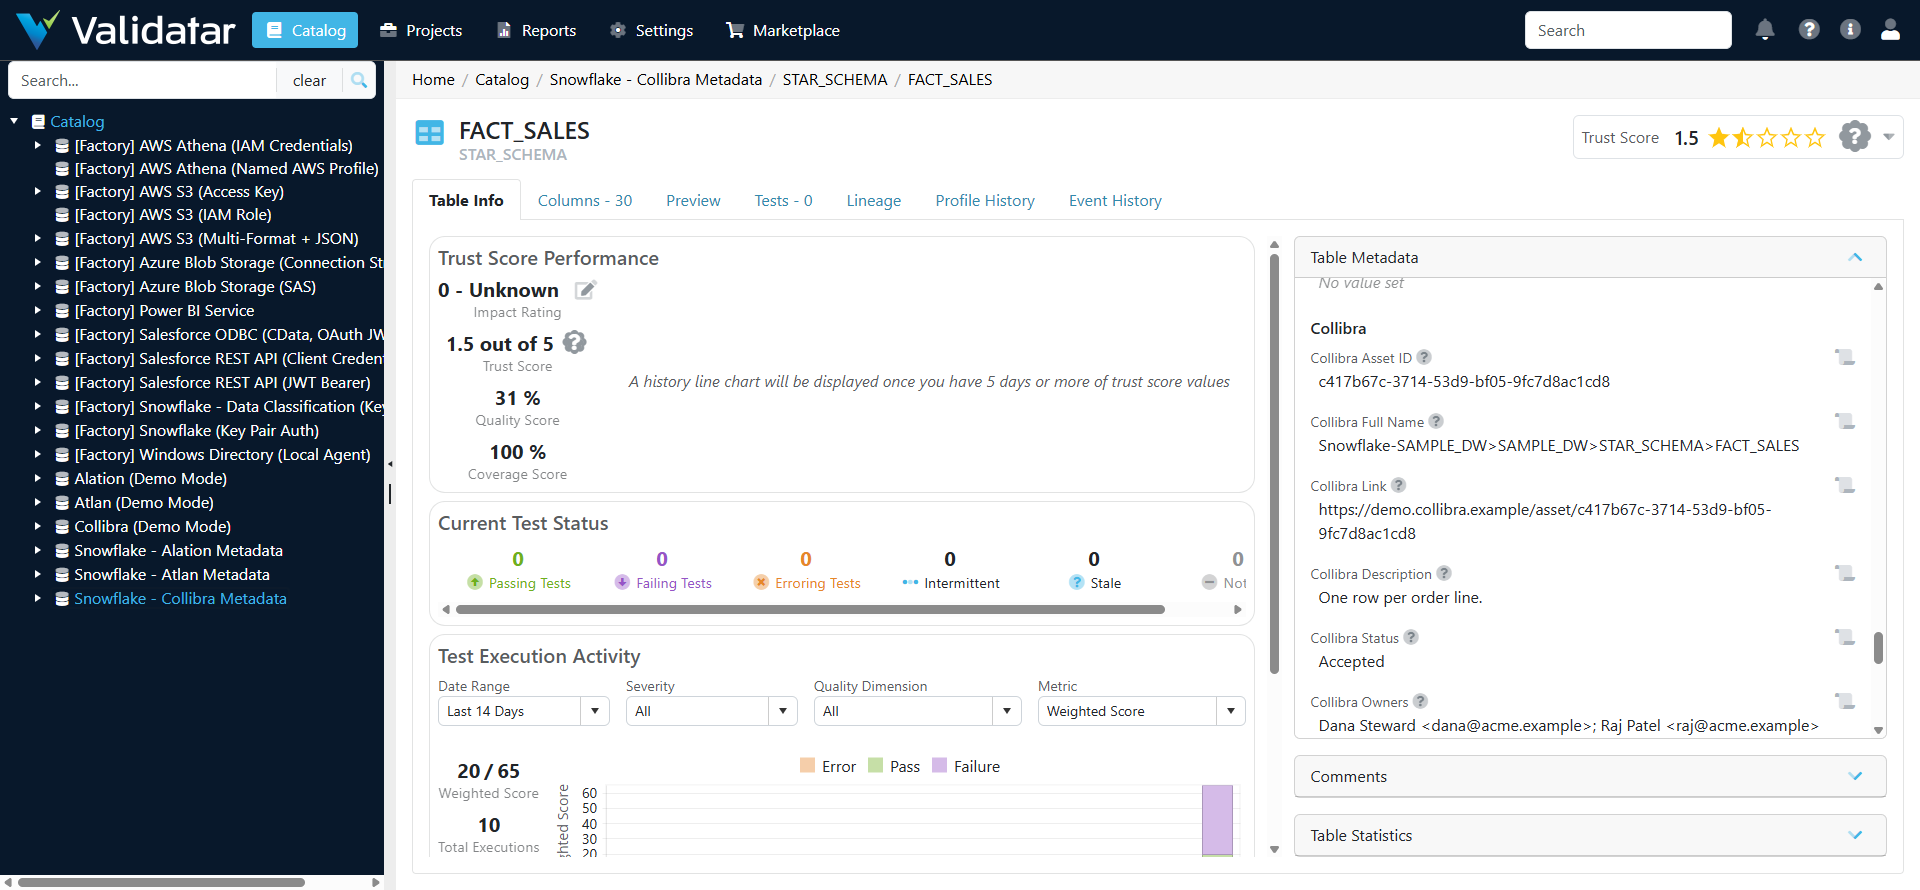
| Table | Collibra Asset ID, Full Name, Link, Description, Status, Owners, Business Stewards, Technical Stewards, Tags, Business Terms, Data Categories, Security Classification, PII, Domain, Community, Last Modified, Last Synced |
| Column (optional) | Collibra Column Asset ID, Link, Description, Status, Tags, Business Terms, Data Classes (accepted only), PII, Synced |
People come back as text, such as Dana Steward <dana@acme.example>, so a name Validatar does not know as a user never fails the run. Tags, terms, categories and data classes come back as lists. Statuses and security classifications are text, because every Collibra instance defines its own values.
The table field Collibra Asset ID is how the Collibra data source template finds the table when it publishes Validatar's results, so run this script before the first publish.
Section 2 of the script controls what comes back:
| Setting | What it does |
|---|---|
TABLE_FIELDS, SCHEMA_FIELDS, DATA_SOURCE_FIELDS, COLUMN_FIELDS |
Turn each field on (True) or off (False). An off field is not sent, so a value set some other way is kept |
INCLUDE_COLUMNS |
Add column-level values. Off by default; it costs one more read of every column of the database, plus one data classification call per 100 columns |
COLLIBRA_ATTRIBUTES |
Copy Collibra text attributes onto tables: {"Data Retention Period": "collibra_retention"}. Create each Validatar field first |
TERM_RELATION_TYPES, CATEGORY_RELATION_TYPES |
The relation types that link business terms and data categories to tables and columns. The defaults are Collibra's own; add yours if your operating model uses others |
A Dropdown field rejects the whole run when it receives a value that is not one of its options, so bring Collibra attributes into Short text fields unless you know every value Collibra can send.
Set up the metadata script
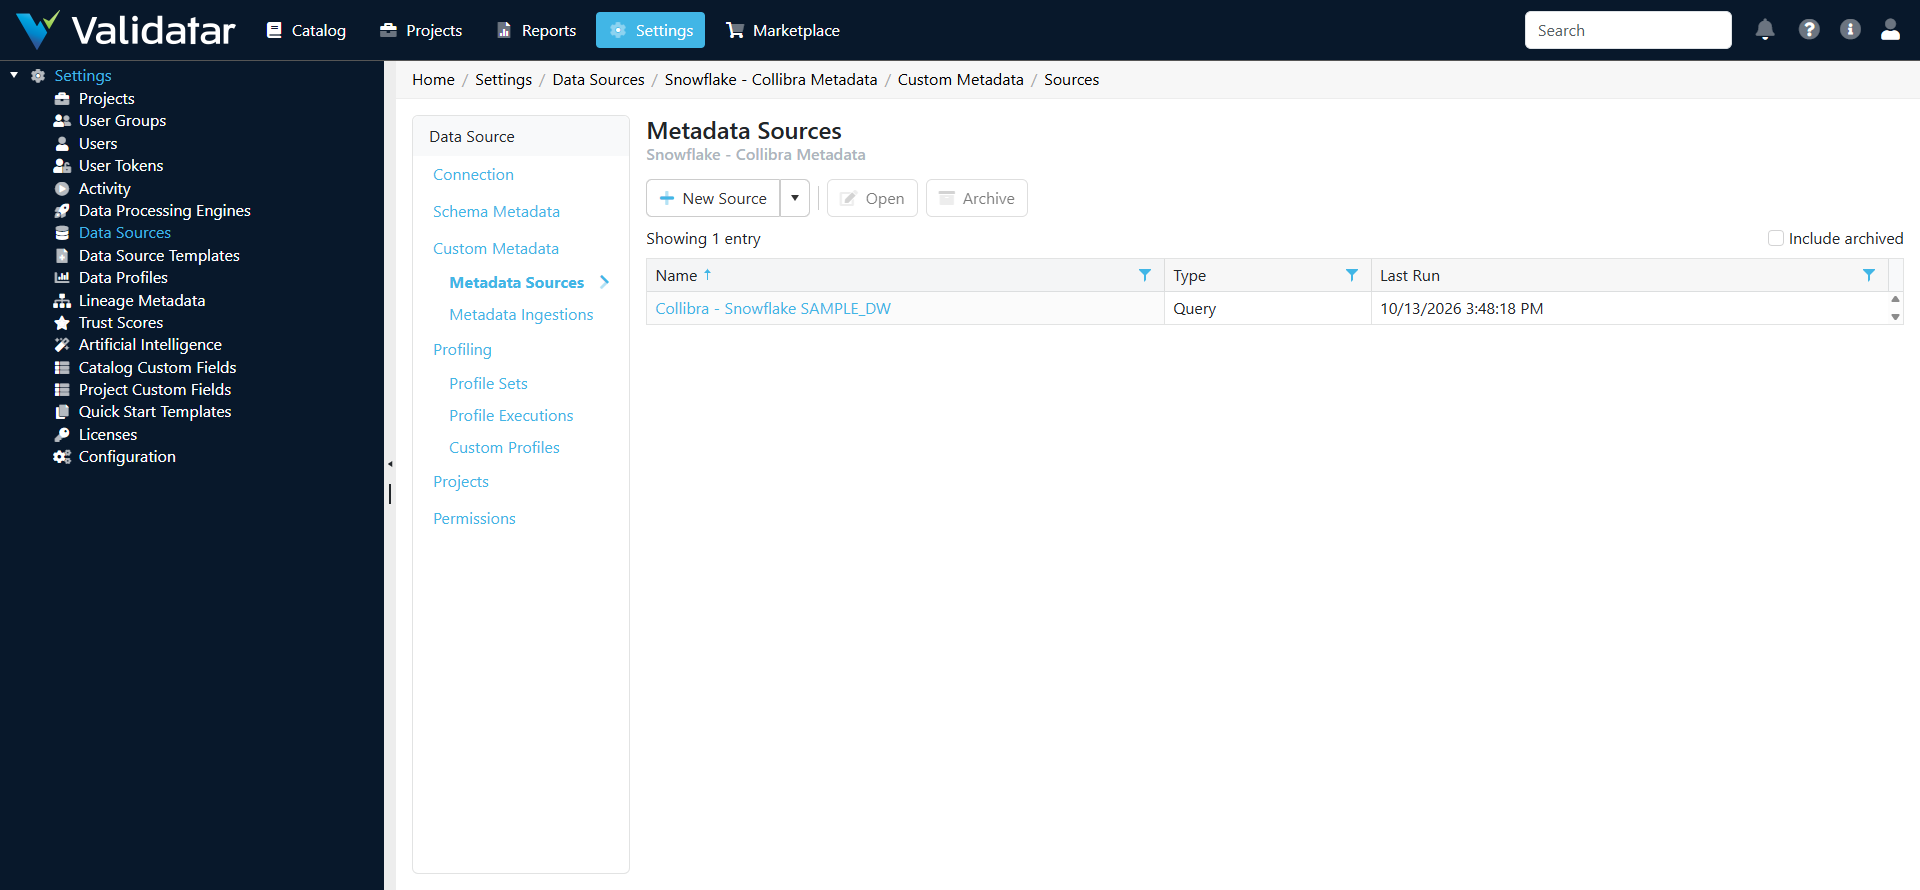
- Open the warehouse data source and go to Custom Metadata > Metadata Sources > New Source > New Query Source.
- Untick Same as primary and Add a connection: Python Script, template Collibra, the agent group if your Python runs on a Data Agent, and your Collibra settings. The Validatar URL and token are not needed for this script.
- Save, then Configure Ingestion Script: paste
collibra_custom_metadata.py, set section 1, and tick Ignore Missing Metadata Objects so Collibra assets Validatar has not cataloged are skipped instead of failing the run. - Preview Script shows the rows for each level before anything is written.
- Update Ingestion Script, Save, Refresh Now, then Set Refresh Schedule (usually daily). Metadata Ingestions lists what was added, modified and skipped at each level.
Note: Validatar gives each data source one custom metadata connection, shared by all its metadata sources. If the data source already has one, for example for the Alation or Atlan integration, step 2 shows that connection with Edit in place of Add. Editing it changes the connection for the existing sources too, so one data source takes its catalog metadata from one catalog.
Set up the lineage script
In section 1, list each Collibra database with the Validatar data source for the same warehouse:
DATA_SOURCES = [
    ("Snowflake-Connection>SAMPLE_DW", 12),   # (Collibra database full name, Validatar data source id)
]
LINEAGE_LEVEL = "table"     # or "column"
By default the script reads business lineage: the "Data Element targets Data Element" relations that Collibra Data Lineage writes between the columns it has stitched to catalog assets. Collibra keeps no table-level lineage relation, so table lineage is rolled up from those column edges. Lineage between two listed databases is included; an edge whose other end is in a database you did not list is left out.
- Go to Settings > Lineage Metadata > Sources > New Source > New Query Source.
- Add a connection: Python Script, template Collibra, the same Collibra settings, plus Validatar Base URL and Validatar API Token. The script uses the token to read the catalog, so it only sends edges whose two ends Validatar has cataloged: one unknown table fails a whole lineage batch.
- Configure Ingestion SQL: paste
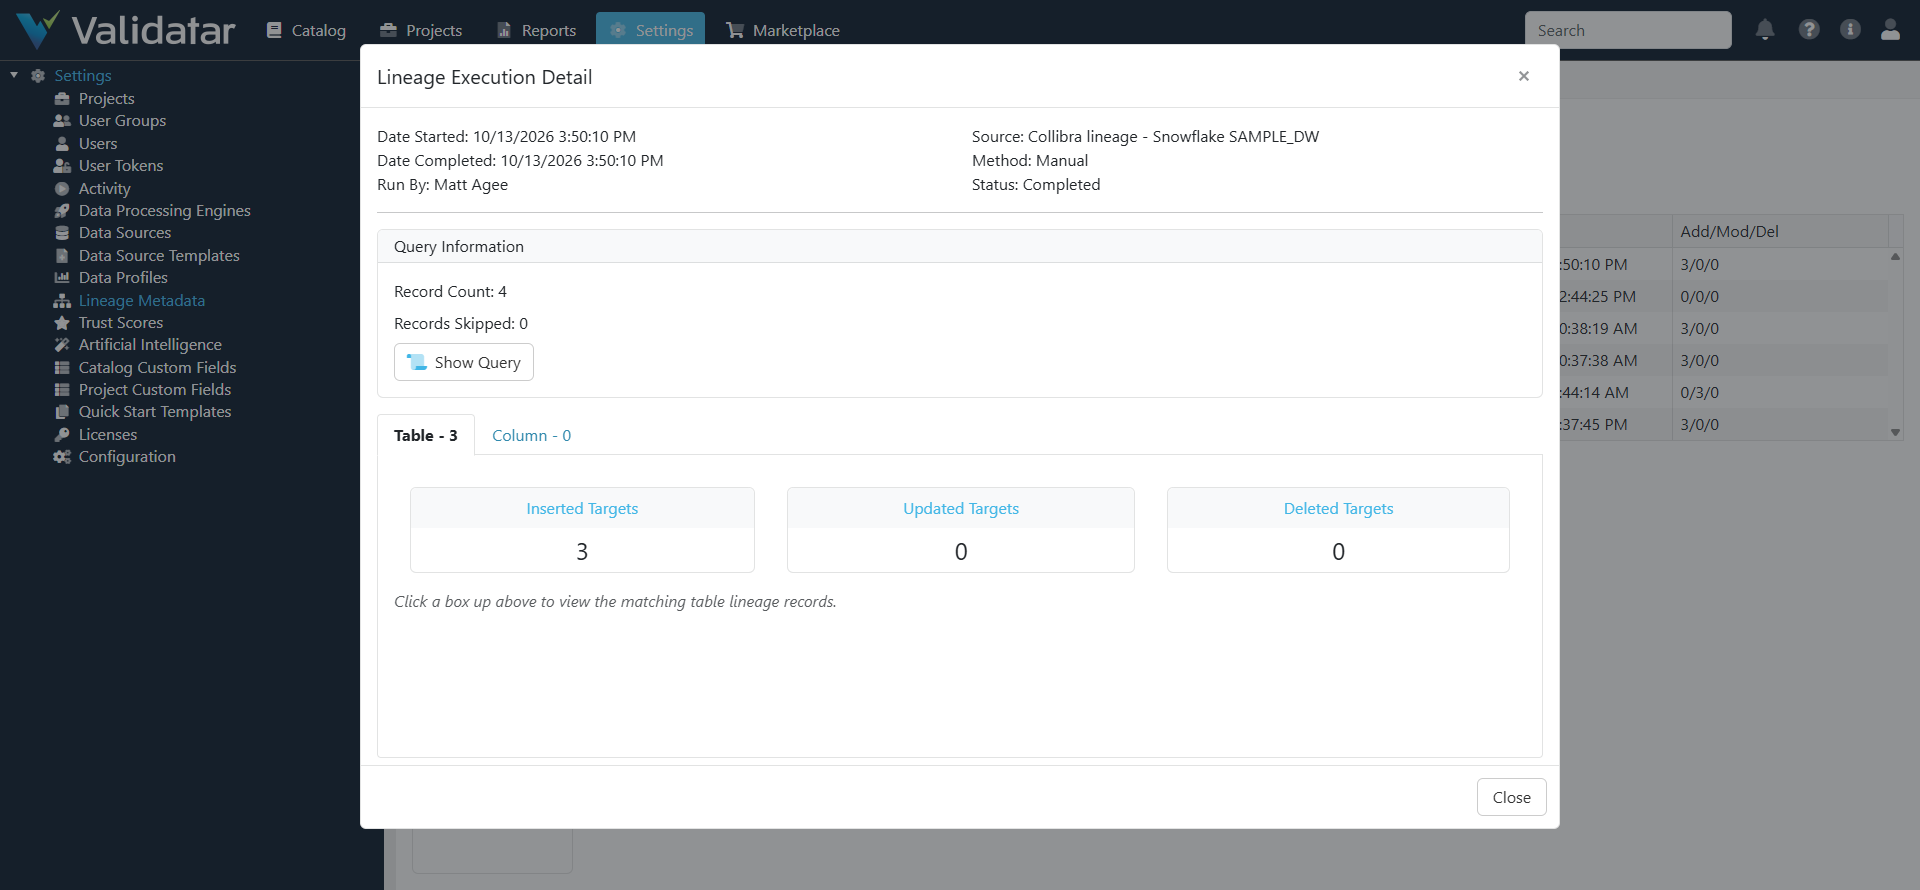
collibra_lineage.py. Preview Script shows the edges. - Update Ingestion SQL, Save, then Run Import. Wait on the page while it validates the query. Validatar then asks which data source each server and database pair belongs to. When more than one Validatar data source points at the same warehouse and database, it suggests one of them, so check that the choice matches the Validatar id in
DATA_SOURCESbefore you choose Run. - Set Refresh Schedule (usually weekly).
| Setting | What it does |
|---|---|
DATA_SOURCES |
Pairs of (Collibra database full name, Validatar data source id) |
LINEAGE_LEVEL |
"table" or "column" |
ONLY_SCHEMAS |
Only edges whose target is in these schemas |
LINEAGE_RELATION_TYPES |
The relation types that carry column lineage. The default is the one Collibra Data Lineage writes |
USE_TECHNICAL_LINEAGE |
Preview. Reads Collibra's technical lineage graph instead of the relations, for lineage that is harvested but not stitched. It makes one call per column, and Collibra has not yet added these read endpoints to its published API reference |
TRANSFORMATION_TEXT |
Written to each edge's transformation, which Validatar requires |
The run message counts the edges left out. Each run replaces the sources of every target table it sends, so hand-edited lineage on those tables does not survive the next run.
Run from the command line
Use this to see the dataframes before setting anything up in Validatar, or to run the scripts from your own scheduler. Keep the .py files in one folder, install requirements.txt, and set COLLIBRA_BASE_URL, COLLIBRA_AUTH_METHOD (OAuth Client or Basic), the OAuth client id and secret or the user name and password, VALIDATAR_BASE_URL and VALIDATAR_API_TOKEN.
| Command | What it does |
|---|---|
python collibra_custom_metadata.py |
Prints what would be written |
python collibra_custom_metadata.py --apply |
Writes it to the data source in VALIDATAR_DATA_SOURCE_ID (section 3 of the script) |
python collibra_lineage.py |
Writes collibra_lineage.csv, which a Validatar File lineage source can also load |
python collibra_setup.py |
Prints the Collibra setup plan; --apply creates what is missing |
Try it without Collibra
Set Demo Mode to Yes on the Collibra connection in Validatar, or set COLLIBRA_DEMO_MODE=1 on the command line. The scripts then answer from a built-in sample instance, and nothing is sent to Collibra. The lineage script still reads the Validatar catalog, so it needs the Validatar URL and token even in Demo Mode.
| Sample database | Full name | What it holds |
|---|---|---|
| SAMPLE_DW | Snowflake-SAMPLE_DW>SAMPLE_DW |
The table names of a common Validatar sample warehouse (STAR_SCHEMA.DIM_CUSTOMER, FACT_SALES, RAW.CLAIM and others) with owners, stewards, tags, business terms, data categories, a classified email column and column lineage. FACT_RETURNS is a planned table a warehouse would not have yet |
| SALES_DB | Snowflake-PROD>SALES_DB |
Orders and customers, and an obsolete raw feed that still feeds a table |
| crm | PostgreSQL-CRM>crm |
A stale database with few owners or descriptions |
Troubleshooting
| Symptom | Fix |
|---|---|
| "Collibra database ... not found" | Copy the full name from the Collibra data source's catalog (schema Database), and check that the integration's user can read the database's domain |
| 401 on every call | The OAuth application's secret was regenerated or the application deleted, or the Basic password changed. Update the credentials on each Collibra connection |
| HTTP 429, or runs slow down | The OAuth application's token pool or Collibra's throttling was reached. The client waits and retries. Use one OAuth application for Validatar alone, or Basic sign-in |
| A GraphQL error naming a field or filter | Collibra is older than 2024.02. The scripts need the Knowledge Graph API |
| The run succeeds but a field stays empty | Import the Collibra Catalog Custom Fields set, and check that any mapped key matches a Validatar field |
| Business terms or categories are empty | Your operating model links them with other relation types. Add their public ids to TERM_RELATION_TYPES or CATEGORY_RELATION_TYPES |
| The run fails on a missing table or column | Tick Ignore Missing Metadata Objects in Configure Ingestion Script |
| No lineage edges | Lineage is harvested but not stitched into relations. Check stitching in Collibra Data Lineage, or try USE_TECHNICAL_LINEAGE = True |
| Lineage appears on the wrong data source | Run Import again and pick the right data source in the mapping step |
| "Validatar base URL is required" from the lineage script | Fill Validatar Base URL and Validatar API Token on the connection |
Related
- Collibra Integration
- Collibra Catalog Custom Fields
- Collibra Data Source Template
- Collibra Setup for Validatar
- Collibra Instance Health Checks
Note: The scripts are built from Collibra's documentation and published OpenAPI specifications, and have been tested offline and against a built-in sample Collibra instance. Against that instance the metadata script returned 2 schemas and 10 tables on SAMPLE_DW, and the lineage script returned 4 table edges. Inside Validatar, run as a Custom Metadata source on a Snowflake data source, the metadata script stored 6 data source, 12 schema, 102 table and 78 column values, skipping the one table Validatar had not cataloged; run as a Lineage Ingestion source, the lineage script loaded 4 edges. They have not yet run against a live Collibra instance, so expect small adjustments after your first live run.